
In the high-stakes world of modern business, a Disaster Recovery (DR) plan is often treated like a fire extinguisher: something you hope you never have to use, but assume will work perfectly the moment you need it. However, for UK SMEs, this "set it and forget it" mentality is a dangerous liability. Technology evolves, threat landscapes shift, and your business infrastructure is constantly changing as you grow. A DR plan that was robust eighteen months ago may be functionally useless today. If a ransomware attack or a catastrophic server failure hits, a failed recovery attempt isn't just an inconvenience—it can be an existential threat to your business. The cost of prolonged downtime or permanent data loss far outweighs the investment in preparedness. Testing is not a bureaucratic box-tick; it is the only way to ensure your business survives the inevitable.
What a Disaster Recovery Plan actually means
To be clear, a Disaster Recovery plan (DRP) is a documented, structured approach that details how an organisation will respond to an unplanned incident that disrupts its IT systems, applications, or data. It is specifically focused on the technical aspects of restoring operations after a disaster. This is distinct from, though closely related to, a broader Business Continuity Plan (BCP), which addresses the continuous operation of all business functions, not just IT.
Essentially, a DRP outlines the steps, resources, and personnel required to bring critical IT infrastructure back online. It covers everything from data backups and restoration procedures to server failover, network recovery, and application re-instatement. The objective is to minimise downtime and data loss, ensuring that your business can resume normal operations as quickly and efficiently as possible, even after a significant technical failure or cyber incident. Without a current, tested plan, recovery becomes an expensive, chaotic, and often unsuccessful exercise in guesswork.
Why it matters for UK SMEs
For UK businesses, disaster recovery is not merely a best practice; it is a regulatory expectation and a commercial necessity. Ignoring it carries significant legal and financial risks.
Under the UK GDPR, organisations are required to implement appropriate technical and organisational measures to ensure a level of security appropriate to the risk. This explicitly includes the ability to restore the availability and access to personal data in a timely manner in the event of a physical or technical incident. The Information Commissioner’s Office (ICO) takes a dim view of organisations that cannot demonstrate this capability. A failure to recover data effectively after a breach or system failure can compound the initial incident, leading to more severe penalties and scrutiny.
If your SME has achieved or is working towards Cyber Essentials or Cyber Essentials Plus certification, you are already aware that business continuity, including robust backup and recovery, is a core component. The National Cyber Security Centre (NCSC) explicitly highlights the importance of regular testing to verify that your backup and recovery solutions are functional. This isn't just about ticking a box for certification; it's about proving you have a viable defence.
Failure to prove that you have tested your recovery capabilities can lead to:
- Hefty ICO Fines: If a breach occurs and you cannot recover data, the ICO will scrutinise your preparedness. Demonstrating a tested, functional DR plan can mitigate the severity of any enforcement action, whereas a lack of one will almost certainly exacerbate it.
- Reputational Damage: Clients and partners in the UK supply chain are increasingly asking for evidence of robust DR testing as part of their due diligence. A publicised failure to recover can erode trust, damage your brand, and lead to lost contracts. Your ability to recover swiftly is a competitive advantage.
- Loss of Cyber Insurance: Many UK insurers now mandate evidence of regular DR testing as a prerequisite for coverage. If you haven't tested, your claim may be denied, leaving you to bear the full financial burden of a recovery effort, which can be considerable.
- Operational Paralysis: Beyond the regulatory and reputational concerns, the most immediate impact is on your day-to-day operations. Prolonged downtime means lost revenue, missed deadlines, inability to serve customers, and potential breaches of service level agreements with your own clients. For many SMEs, this can quickly become an existential threat.
How to implement and test your Disaster Recovery Plan
Many organisations operate under the assumption that an annual "tabletop" exercise satisfies compliance requirements. While better than nothing, the pace of digital transformation in the UK SME sector makes an annual cadence increasingly obsolete. When your infrastructure changes—whether through moving to the cloud, onboarding new software-as-a-service (SaaS) tools, or shifting to hybrid working—your recovery requirements shift with it. If you have updated your operational processes but failed to update your DR documentation, your recovery time objective (RTO) will almost certainly be missed.
We recommend a tiered testing approach. While a full-scale simulation may be an annual event, smaller, targeted component tests should occur quarterly. This ensures that the "muscle memory" of your IT team or your managed service provider (MSP) remains sharp, and that any technical drift is caught long before it becomes a disaster.
Not all tests are created equal. To get a true picture of your resilience, you need to employ a variety of testing methodologies that increase in complexity over time.
1. Identify Your Critical Business Functions
A common mistake SMEs make is trying to recover everything at once. In a disaster, you need to prioritise. Your DR plan should be built around your "Crown Jewels"—the systems that, if offline, would cause your business to cease trading.
To identify what to test, conduct a Business Impact Analysis (BIA):
- Map Dependencies: Does your CRM rely on a specific database? If the database isn't recovered first, the CRM will fail. Understand these linkages.
- Establish RTO/RPO: How many hours of downtime can you afford for each critical system (Recovery Time Objective)? How much data loss is acceptable (Recovery Point Objective)? These metrics dictate the technology and processes required for recovery.
- Document Recovery Sequences: Create a "Runbook" that dictates the order in which systems must be brought back online. This is a step-by-step guide for your team.
When you test, you aren't just testing the technology; you are testing this sequence. If you find that the payroll system takes four hours to restore but your staff need it in two, you have identified a gap that needs to be addressed through better hardware, cloud solutions, or improved processes.
2. Prepare for the Test
Before any actual testing begins, ensure you have:
- Clear Objectives: What exactly are you trying to validate in this test? Restoration of a single server? An entire branch office?
- Designated Team: Who is involved? What are their roles and responsibilities?
- Communication Plan: How will internal and external stakeholders be informed during a simulated disaster?
- Test Environment: For full-scale tests, an isolated environment is crucial to avoid impacting live operations.
- Updated Documentation: The DR plan, runbooks, and contact lists must be current.
3. Choose Your Testing Methodologies
Tabletop Exercises (The Discussion)
This is a low-stress, low-impact way to begin. Gather your stakeholders—IT leads, management, and key department heads—and walk through a hypothetical scenario (e.g., "Our primary server has been encrypted by ransomware," or "Our office has lost power for an extended period").
- The Goal: Identify gaps in communication, decision-making, and documentation. It's about validating the plan's logic and the team's understanding.
- The Outcome: An updated incident response plan with clear lines of authority, refined communication protocols, and identified resource shortfalls. These should happen at least annually, or whenever there are significant changes to the business or IT team.
Component Testing (The Technical Check)
This involves testing specific parts of your infrastructure. For example, can you restore a single critical file from a backup? Can you failover your email system to a secondary server? Can you successfully restore a virtual machine?
- The Goal: Validate that individual backup sets are not corrupted and that recovery tools function as expected. This helps catch minor issues before they become major problems.
- The Outcome: Confirmation that specific recovery procedures work, identification of faulty backups or outdated software, and improved confidence in individual system recovery. These should occur quarterly for critical systems. On a recent client tenant audit for a Surrey-based logistics firm with 25 staff, we found that 3 out of 5 critical application backups had not been tested for over a year, and one was failing silently. Regular component testing would have caught this well in advance.
Full-Scale Simulation (The "Game Day")
This is the most rigorous test. You simulate a total site failure and attempt to recover your entire environment, or at least your identified "Crown Jewels." This should be performed in an isolated environment to avoid disrupting your live operations. It's a dress rehearsal for the worst-case scenario.
- The Goal: Confirm that your RTO (Recovery Time Objective) and RPO (Recovery Point Objective) are actually achievable in practice across your integrated systems. It tests not just technology, but also team coordination under pressure.
- The Outcome: A definitive assessment of your DR capabilities, identification of bottlenecks, validation of the recovery runbook, and a realistic understanding of your recovery times. This should be an annual event.
4. Post-Test Analysis and Improvement
A test's value lies in what you learn from it.
- Debrief: Immediately after each test, conduct a debriefing session with all participants. What went well? What failed? What could be improved?
- Document Findings: Record all successes, failures, unexpected issues, and lessons learned.
- Update Plan: Revise your DR plan, runbooks, and related documentation based on the test results. This might involve changing procedures, investing in new technology, or providing further staff training.
- Retest: If significant changes are made, a retest of those specific components or procedures may be necessary to validate the improvements.
Common mistakes we see
The biggest hurdle to regular DR testing is often the belief that SMEs are "too small" to be targeted or that a disaster is an improbable event. The reality in the UK is stark: cybercriminals target SMEs precisely because they have valuable data but often lack the enterprise-grade security budgets of larger corporations. Beyond that, technical failures, human error, and natural events affect businesses of all sizes.
Here are some common pitfalls we observe:
- Relying solely on your MSP without oversight: While a managed service provider is vital, the ultimate responsibility for business continuity lies with the business owner. Ensure you are getting clear, documented reports from your provider after every test, and understand what those reports actually mean for your business's resilience.
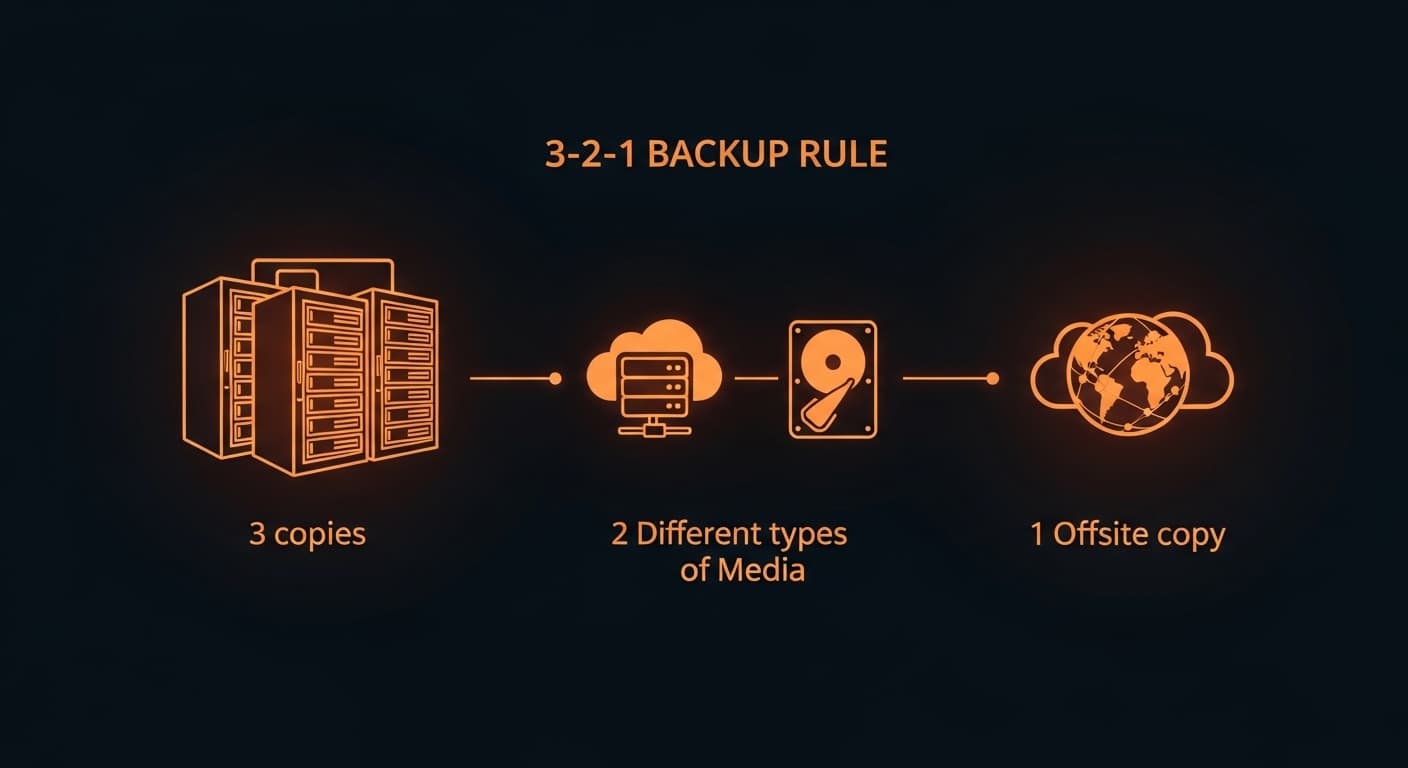
- Ignoring Cloud Backups: Just because your data is in the cloud (Microsoft 365 or Google Workspace) does not mean it is automatically recoverable in a disaster. "Syncing" is not the same as "backing up." SaaS providers have their own recovery objectives, which may not align with yours. Ensure your cloud data is protected by a secondary, immutable backup solution that you control.
- Documentation Decay: If your DR plan is a PDF document stored on the server that just crashed, you have a problem. Keep physical copies or offline, encrypted copies of your recovery plan. More broadly, if documentation isn't updated whenever there's a change to your IT environment, it quickly becomes irrelevant.
- Untested Assumptions about RTO/RPO: Many SMEs assume they can be back up and running in a few hours, but have never actually timed a full recovery. An untested RTO is merely a wish.
- Lack of Staff Training: Even the best plan is useless if the people executing it don't know their roles or haven't practised them. DR is a team effort.
- Not Testing the Entire Chain: It's common to test data restoration but forget to test if the applications can then use that data, or if network connectivity to external services is re-established. The whole process, from power-on to user login, needs validating. Frankly, it's surprising how often this fundamental step is overlooked.
Key Takeaways
- Frequency is Key: Move beyond annual testing. Aim for quarterly component tests and an annual full-scale simulation.
- Documentation Matters: A test is only as good as the lessons learned. Always document failures and update your recovery runbooks immediately.
- Regulatory Compliance: Regular testing is a requirement for GDPR compliance and is often a prerequisite for cyber insurance and supply chain contracts.
- Prioritise Recovery: Use a Business Impact Analysis to ensure you are recovering your most critical assets first.
- Test the Human Element: Disaster recovery is as much about communication and decision-making as it is about technology. Ensure your team knows their roles when the "panic button" is pressed.
- Verify, Don't Assume: Never assume a backup is working. A backup is only a backup if you have successfully restored from it.
Disaster recovery is not a one-off project; it is a continuous cycle of preparation, testing, and improvement. By treating your DR plan as a living document, you ensure that when the unexpected happens, your business remains resilient, compliant, and ready to bounce back.
If the prospect of designing, implementing, and regularly testing a comprehensive disaster recovery plan feels overwhelming, you are not alone. Many UK SMEs lack the internal resources or specialist expertise to manage this effectively. Bringing in external experts can provide the necessary guidance, tools, and impartial assessment to build a truly resilient recovery strategy.
To take the next step